
EmbeddingGemma 2: Google’s Lightweight Multimodal AI Model Explained
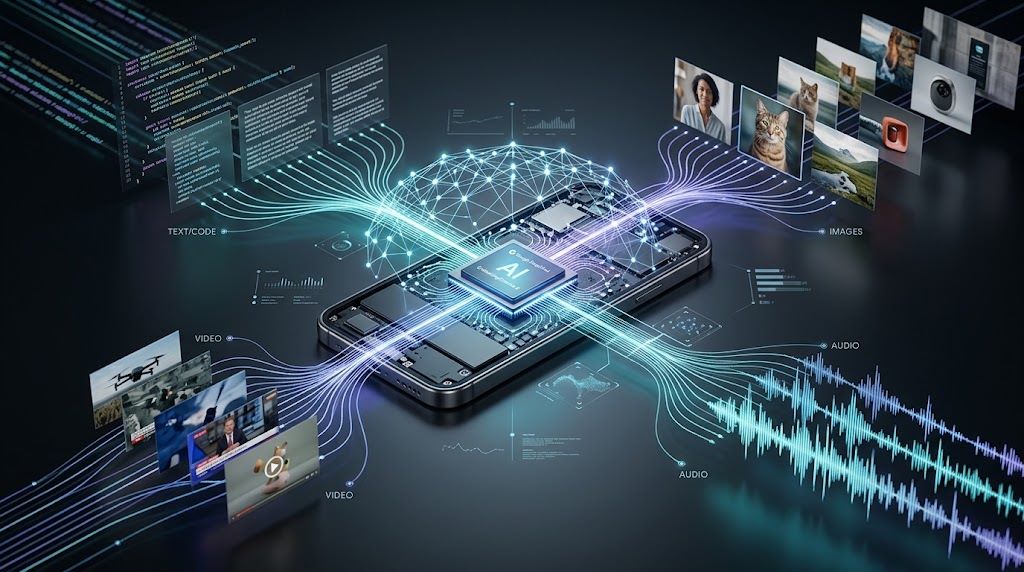
Google DeepMind has introduced EmbeddingGemma 2, a new lightweight multimodal embedding model designed to help developers understand and connect text, images, audio, video, and code on local devices.
Unlike traditional embedding models that primarily focus on text, EmbeddingGemma 2 is designed to place different types of information into a shared embedding space. This means developers can build applications where a text query can be matched with an image, video clip, or audio recording without relying entirely on cloud-based processing.
With 740 million parameters and support for on-device inference, EmbeddingGemma 2 is aimed at developers who want powerful semantic search and retrieval capabilities while keeping computing requirements relatively low.
What Is EmbeddingGemma 2?
EmbeddingGemma 2 is a multimodal embedding model developed by Google DeepMind. It is designed to convert different forms of information into numerical representations called embeddings.
These embeddings allow software to determine how closely related two pieces of information are.
For example, a developer could use a text query such as “a meeting about product planning” to search through a collection of audio recordings or videos. Instead of matching only exact words, the system can use semantic relationships to identify relevant content.
The model supports combinations of:
- Text
- Images
- Audio
- Video
- Code
This cross-modal capability makes EmbeddingGemma 2 particularly interesting for search, retrieval, recommendation, classification, and AI-agent applications.
A Multimodal Model Built for Local Devices
One of the biggest characteristics of EmbeddingGemma 2 is its focus on on-device AI.
Rather than sending every piece of data to a remote server, applications can process embeddings locally. This can be useful for products where privacy, offline access, or low latency are important.
Google says the model can operate within relatively tight hardware constraints. After quantization, the text-only configuration can require around 191 MB of active RAM on a Google Pixel 11 Pro, while the full multimodal configuration can require approximately 567 MB.
That opens the possibility of embedding-powered features running directly on smartphones and other edge devices.
Why Embeddings Matter for AI Applications
Embeddings are an important part of modern search and retrieval systems.
Instead of treating information as simple keywords, an embedding system represents its meaning in a mathematical vector. Similar concepts can therefore be positioned closer together in the embedding space.
This approach is widely used for applications such as:
- Semantic search
- Recommendation systems
- Document retrieval
- Retrieval-augmented generation (RAG)
- Content classification
- AI-agent memory
- Code search
- Media discovery
EmbeddingGemma 2 extends this concept across multiple types of media.
One Embedding Space for Text, Images, Audio and Video
A major feature of EmbeddingGemma 2 is its ability to work across modalities.
Imagine a user has thousands of photographs, videos, and voice recordings stored locally. With a multimodal embedding system, a search application could potentially use a text description to find related media.
For example, a user could search for:
“The video where we discussed the new product launch.”
The system could compare the meaning of the query against locally generated embeddings from video and audio content and identify potentially relevant moments.
This type of cross-modal retrieval can make large personal and business media collections easier to search.
Improved Performance for Code Search
EmbeddingGemma 2 is not limited to consumer media applications. It also targets software development workflows.
According to Google, the model achieved a substantial improvement in the MTEB Code benchmark, increasing from 68.76 with EmbeddingGemma to 78.68.
That improvement could make the model useful for applications such as:
- Searching large codebases
- Finding related functions
- Retrieving relevant documentation
- Supporting coding agents
- Locating similar code patterns
- Building local developer tools
For organizations working with large private codebases, local semantic code search could be especially valuable.
8K Token Context Window
EmbeddingGemma 2 also expands its context capability compared with the first-generation EmbeddingGemma.
The new model supports an 8K-token context window, which Google says is four times larger than EmbeddingGemma 1.
The larger context allows the system to process combinations of different media types, including substantial amounts of audio, images, and video frames.
Google describes the capacity as reaching approximately:
- 5.5 minutes of audio
- 29 images
- 58 video frames
- Or combinations of these inputs
This makes the model better suited to applications that need to understand multiple pieces of information together rather than processing every item independently.
Flexible Model Architecture
EmbeddingGemma 2 has been designed with modularity in mind.
For text-only applications, developers can use a smaller configuration, while optional vision and audio encoders can extend the model for multimodal workloads.
The reported configuration includes:
- 270 million parameters for text-focused workloads
- An optional 170 million-parameter vision encoder
- An optional 300 million-parameter audio encoder
- 740 million parameters for the full model
This modular approach means developers do not necessarily need to deploy the complete multimodal system when their application only requires text embeddings.
Smaller Vector Sizes Can Reduce Storage Requirements
Embedding systems can generate large numbers of vectors, especially when they are used with extensive local databases.
EmbeddingGemma 2 uses Matryoshka Representation Learning (MRL) to provide more flexibility in how embeddings are stored.
Developers can reduce the vector representation from 768 dimensions to:
- 512 dimensions
- 256 dimensions
- 128 dimensions
Reducing vector dimensions can lower storage and memory requirements. Google says this approach can provide up to six times less storage usage for local vector databases and related memory requirements.
For applications running on smartphones, laptops, or other resource-constrained hardware, that reduction could be significant.
Privacy and Offline AI Applications
On-device processing is becoming increasingly important as AI applications handle more personal and sensitive information.
EmbeddingGemma 2 can help developers build retrieval systems where data does not always need to leave the device.
Potential benefits include:
Better Privacy
Sensitive documents, recordings, photographs, and other personal information can potentially remain on the user’s device.
Lower Latency
Local processing can eliminate some of the network delay associated with sending information to a remote server and waiting for a response.
Offline Functionality
Applications can potentially continue working without an internet connection, depending on the rest of the application architecture.
Lower Cloud Dependency
Developers may be able to reduce the amount of embedding-related processing performed through cloud services.
These advantages make local embeddings particularly interesting for privacy-focused productivity and enterprise applications.
EmbeddingGemma 2 and On-Device RAG
One of the most interesting applications is retrieval-augmented generation, commonly known as RAG.
A typical RAG system retrieves relevant information from a knowledge base before providing that information to a generative AI model.
With EmbeddingGemma 2, developers can create local retrieval systems capable of working with multimodal information.
When combined with a generative model such as Gemma 4, a device could potentially retrieve relevant documents, images, audio, or video locally before using a generative model to reason about the retrieved information.
This could enable AI assistants that work with private local data without sending the entire knowledge base to a cloud server.
Practical Applications for Developers
EmbeddingGemma 2 could be useful across several categories of software.
Semantic Media Search
Users could search large collections of photographs, recordings, and videos using natural-language descriptions.
Local Document Search
Businesses could create private search tools for documents stored on laptops or local servers.
Video Retrieval
Developers could build systems capable of locating specific moments in long videos using text or audio queries.
AI Coding Tools
The model’s improved code performance could support semantic search across repositories and retrieval for coding assistants.
Recommendation Systems
Embedding-based similarity can help applications identify related content and improve recommendations.
Classification and Routing
Multimodal embeddings can also be used as part of systems that classify information or route content to different workflows.
Tools and Ecosystem
Google is making EmbeddingGemma 2 available through several developer ecosystems.
The model weights are available through platforms including Hugging Face and Kaggle, while developers can also explore optimized on-device implementations.
Google’s AI Edge ecosystem provides tools for deployment through technologies such as MediaPipe and LiteRT.
Developers can also work with popular machine-learning and inference frameworks, including transformers, sentence-transformers, MLX, vLLM, llama.cpp, SGLang, Ollama, and LM Studio.
This broad ecosystem could make experimentation easier for developers who already use open-source AI tooling.
Apache 2.0 License Opens the Door for Wider Adoption
EmbeddingGemma 2 is released under the Apache 2.0 license, which is a commercially permissive open-source license.
For developers and businesses, licensing flexibility can be an important consideration when deciding whether to integrate a model into a commercial product.
Combined with its relatively small size and local inference focus, the licensing model could help EmbeddingGemma 2 reach a wide range of applications.
How EmbeddingGemma 2 Could Change Local Search
Traditional search often depends heavily on keywords.
Multimodal embedding systems can move search toward meaning-based discovery.
Instead of remembering the exact words used in a document, the user could describe what they are looking for. Instead of manually scanning hours of video, they could search for a concept or event.
That shift could be particularly important as smartphones and personal computers accumulate increasingly large collections of documents, photos, recordings, and videos.
EmbeddingGemma 2 vs. Traditional Text Embeddings
The main difference is the range of information that can be represented.
Traditional text embedding models are primarily designed to compare text with other text. EmbeddingGemma 2 expands the approach to include multiple modalities within a shared representation system.
This can make it more suitable for applications where information is not limited to written documents.
For developers, the choice will still depend on the application’s requirements. A simple text-search application may not need the additional complexity of multimodal processing, while media-heavy applications could benefit substantially from it.
What This Means for the Future of Edge AI
The release of EmbeddingGemma 2 reflects a broader trend in artificial intelligence: moving more AI workloads from centralized cloud infrastructure toward personal and edge devices.
Smaller models are becoming increasingly capable, while modern smartphones and laptops are gaining more powerful AI hardware.
If these trends continue, users may increasingly interact with AI systems that understand their local files, media, and applications without continuously sending data to remote servers.
EmbeddingGemma 2 is an example of how embedding technology can become part of that transition.
Final Thoughts
EmbeddingGemma 2 represents a significant step toward practical multimodal AI running directly on consumer hardware.
With 740 million parameters, an 8K-token context window, support for text, images, audio, video and code, flexible embedding dimensions, and a strong focus on local inference, the model targets developers who need semantic retrieval without depending entirely on cloud infrastructure.
Its potential applications range from private document search and AI-powered media libraries to code retrieval, local RAG systems, recommendation engines, and multimodal AI assistants.
As on-device AI continues to develop, models like EmbeddingGemma 2 could make sophisticated search and retrieval capabilities available directly on smartphones, laptops, and other edge devices.
